Unable to find what you're searching for?
We're here to help you find itDesign scalable systems using SLOs, Error Budgets, and Full-Stack Observability. Learn from DevOps Institute-certified trainers through hands-on labs and real-world projects to earn the SRE Practitioner certification.


500K+ certified professionals
Explore Site Reliability Engineering Expansion certification and training courses — delivered live by certified instructors.
Site Reliability Engineering Expansion is a structured approach to managing production systems at scale, published by Google Cloud, that applies software engineering principles to operations to ensure high availability, performance, and resilience of critical services. It forms a core part of Google Cloud’s operations framework, enabling organizations to automate, monitor, and improve system reliability through standardized practices. Key components include Cloud Monitoring for tracking performance and availability metrics, Cloud Logging for centralized log management and analysis, Cloud Trace for identifying latency bottlenecks in distributed systems, Cloud Profiler for continuous performance profiling, and Error Reporting for automatic detection and aggregation of application errors. These tools collectively support SRE practices such as setting service-level objectives (SLOs), managing error budgets, and reducing operational toil. This technology is designed for site reliability engineers, DevOps practitioners, and platform engineers who are responsible for maintaining scalable and resilient cloud systems. It enables them to apply proven SRE methodologies, automate operations, and use data-driven insights to balance feature velocity with system reliability.
SRE Fundamentals
Define SLIs, set SLOs and manage error budgets for services
Observability Tools
Use Prometheus, Grafana and OpenTelemetry for full-stack monitoring
Incident Command
Lead incident response using IMAG or PagerDuty frameworks
Automation Scripts
Write and execute runbooks for common system remediations
Chaos Engineering
Design and run fault injection experiments with Gremlin or Litmus
Infrastructure as Code
Manage cloud resources using Terraform or Pulumi configurations
The building blocks every Site Reliability Engineering Expansion solution is made of
See what your official Site Reliability Engineering Expansion certification looks like. Download a sample — then let our advisors map the fastest path to earning the real one.
 Professional Cloud DevOps EngineerGoogle Cloud Professional Cloud DevOps Engineer
Professional Cloud ArchitectGoogle Cloud Professional Cloud Architect
AWS Certified DevOps Engineer - ProfessionalAWS Certified DevOps Engineer - Professional
CKACertified Kubernetes Administrator
Terraform AssociateHashiCorp Certified: Terraform Associate
DevOps Engineer ExpertMicrosoft Certified: DevOps Engineer Expert
Official credential badges — shareable on LinkedIn
Four formats. One quality standard. Every option comes with the same expert instructors, official courseware, and money-back guarantee.
Every factor that determines whether you actually pass your Site Reliability Engineering Expansion exam — rated across every training format available.
| Criteria | Koenig | ALP Provider | Legacy Provider | Self-Paced Platform | Free Platform |
|---|---|---|---|---|---|
| Trainer Quality & Credentials | |||||
| Accredited Instructors | Partial | ||||
| Live Instructor-Led | Partial | ||||
| 1-on-1 Private Training | |||||
| DevOps Institute Authorisation | |||||
| Official Partner Status | |||||
| Official Courseware | Partial | ||||
| Training Credits Accepted | |||||
| Flexibility & Access | |||||
| Any-Day/Flexi Start | |||||
| On-Site/Fly-Me-Trainer | Partial | ||||
| Global Delivery Reach | Partial | Partial | |||
| Results & Trust | |||||
| Exam Pass Rate | 95% (Verified Audit) | Not disclosed | Not published | Not tracked | Variable |
| Entry Price (Fundamentals) | ~$745 · best value | ~$1,500+ | ~$1,400+ | $15-30/mo (MOOC) | Open-source resources |
| Verified Learner Reviews | 18,400+ · 4.9★ | Limited | Limited | High volume | N/A |
Data sourced from public pricing pages and review platforms. Accurate as of March 2026. Partial = available in select regions only.
Verified reviews from learners certified on Azure, AI, Security, and more.
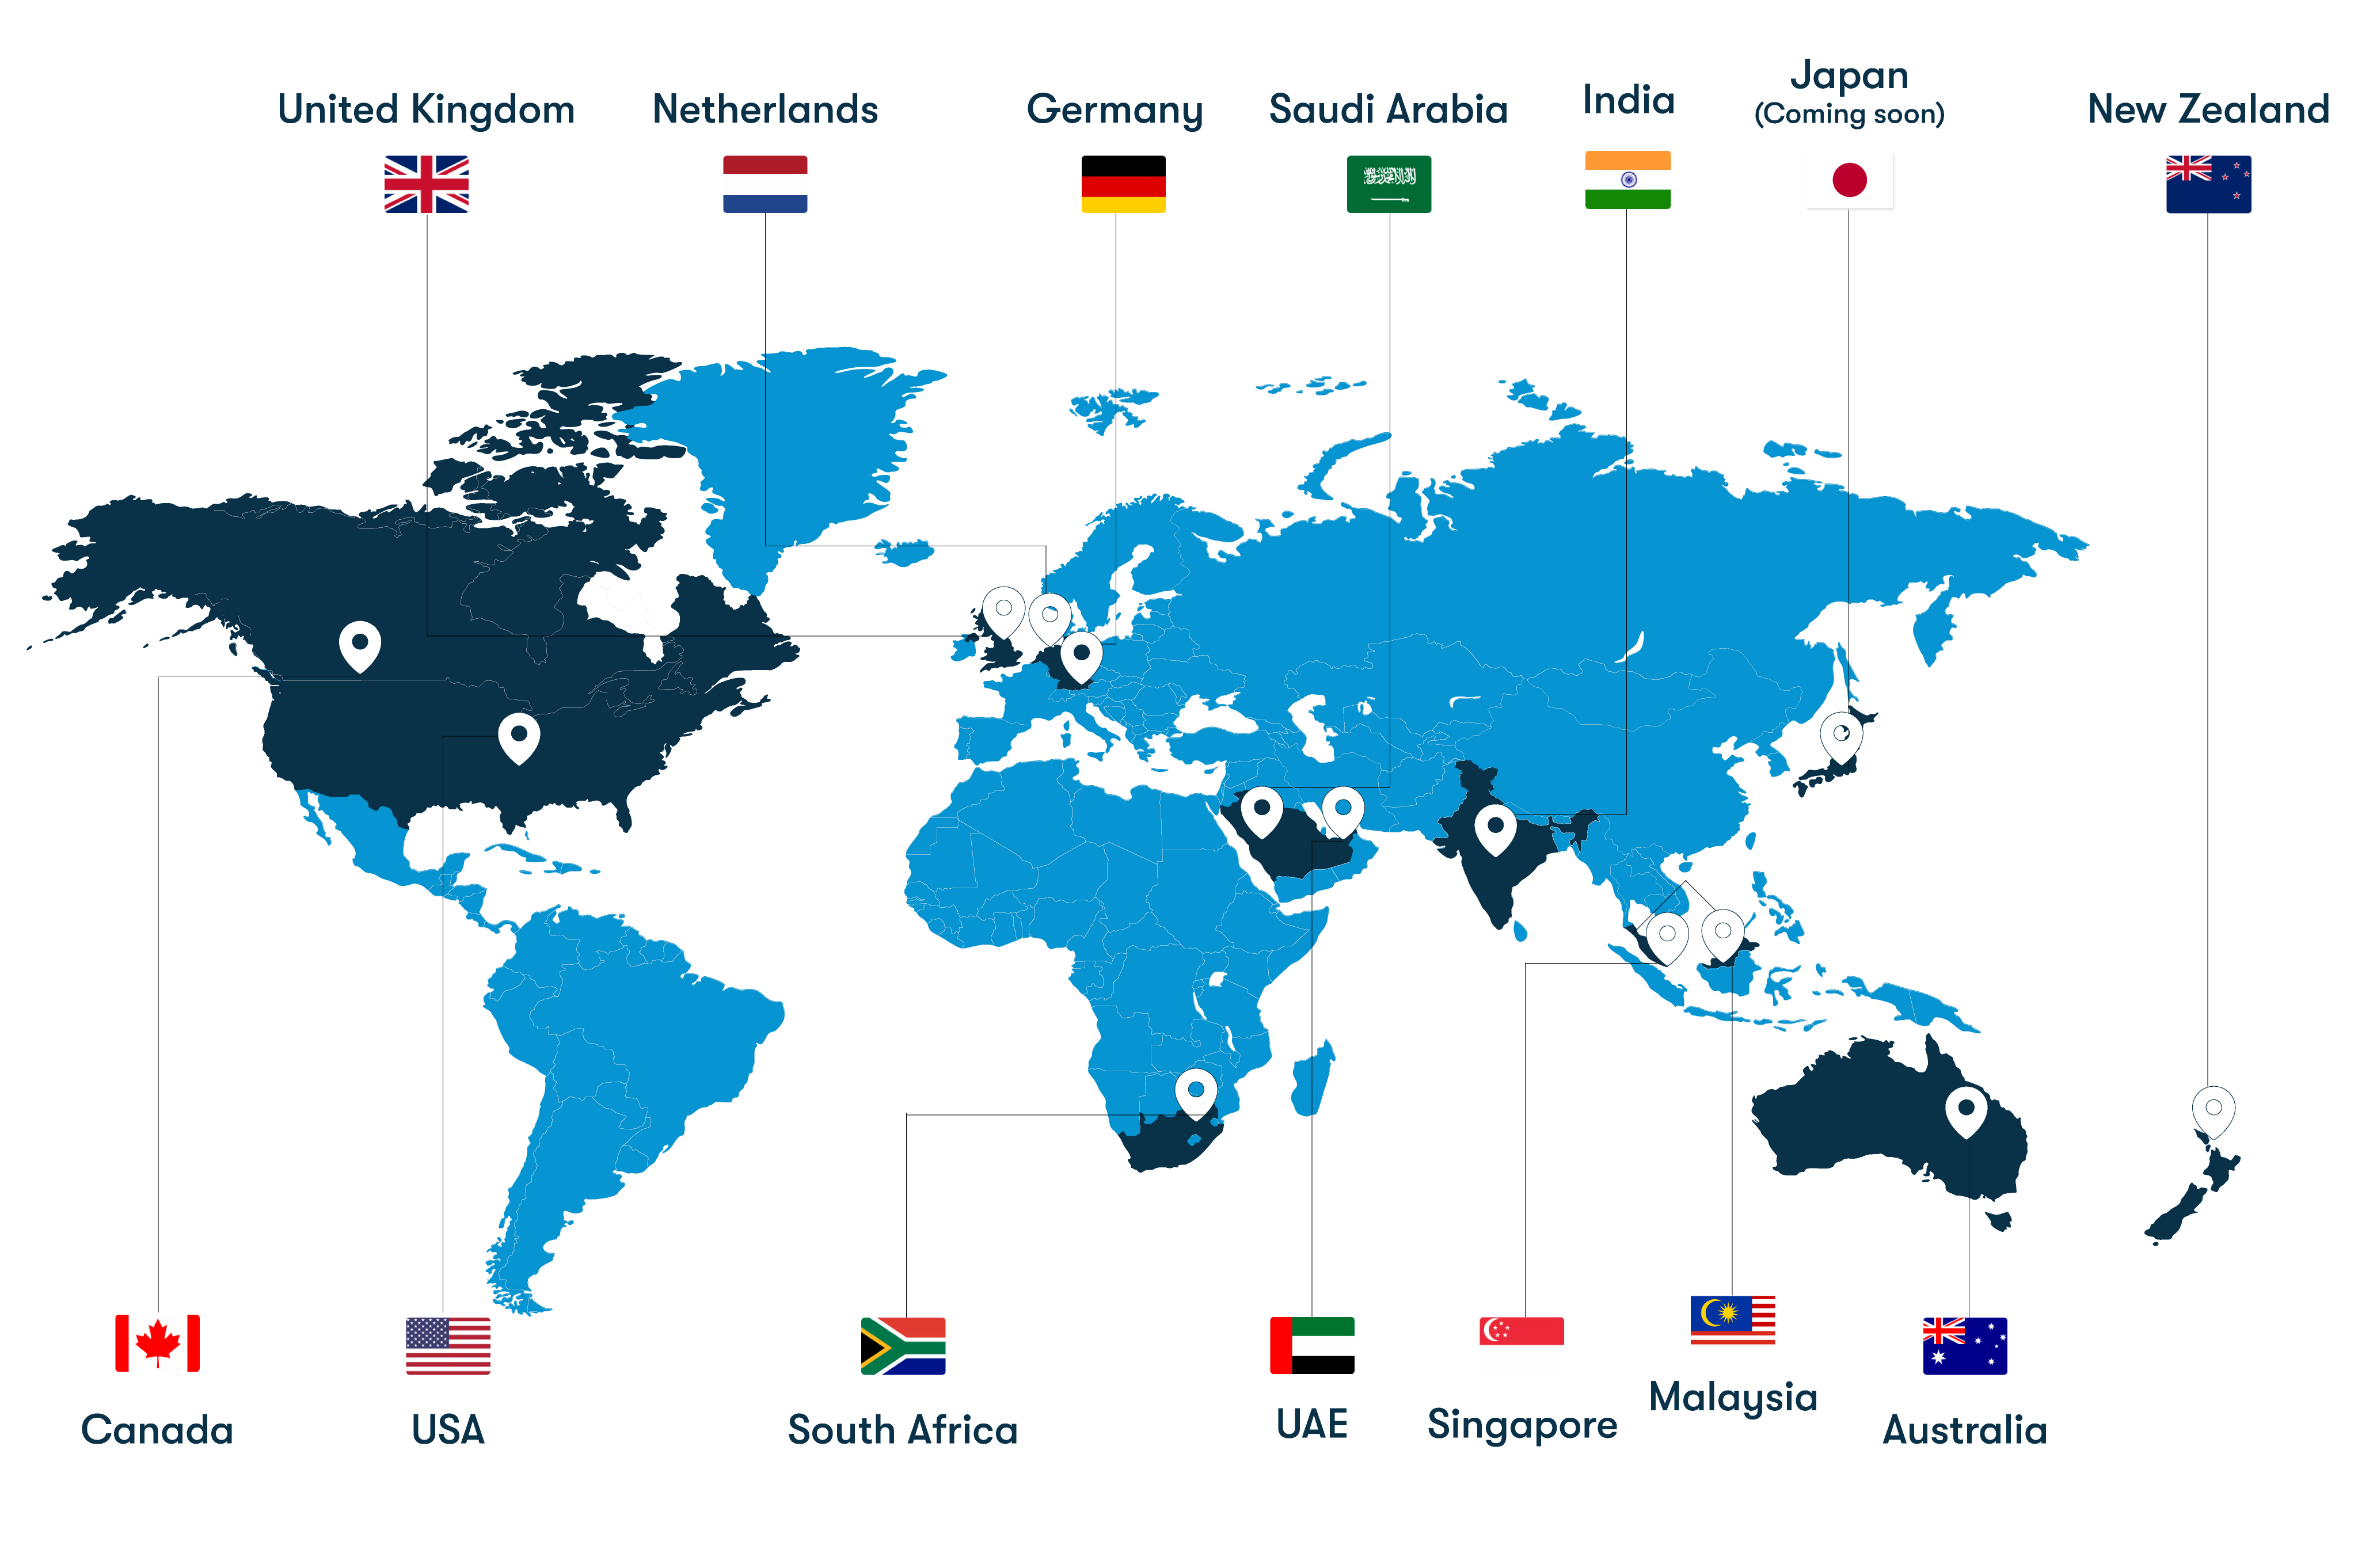
From our headquarters in India to training centers across UAE, Iraq, Saudi Arabia, UK, USA, Singapore, Australia, and more — Koenig delivers Microsoft certification training in 50+ countries.